
Memoria benchmark
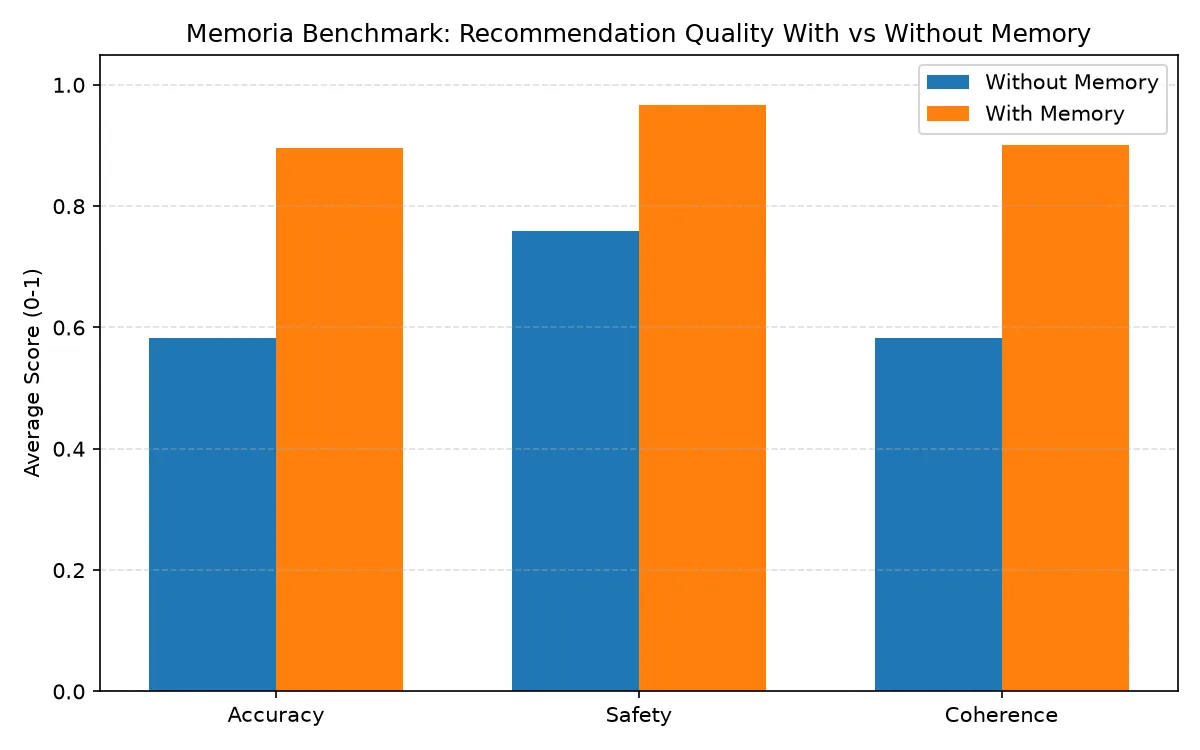
The same Qwen model answers 12 realistic requests twice, once with stored user memories and once without. Memory-augmented replies score 77.6% higher on average.
Method
- Model:
qwen-plus. Script: scripts/benchmark.py. - A fixed test profile is stored as memories: allergies (peanuts, shellfish), a vegetarian diet, interests (hiking, cooking, machine learning) and goals (eat healthier, learn Python).
- Each scenario runs once without memories and once with memories retrieved through
retrieve_context. - Replies are scored from 0 to 1 on accuracy, safety and coherence. The composite is the mean of the three.
Averages
| Metric | Without memory | With memory |
|---|---|---|
| Average accuracy | 0.58 | 0.90 |
| Average composite | 0.64 | 0.92 |
| Average improvement | n/a | +77.6% |
All 12 scenarios
Scores are accuracy / safety / coherence. Two scenarios scored slightly lower with memory, and three did not change. Improvement is the change in composite score.
| Scenario | Without | With | Improvement |
|---|---|---|---|
| Recommend a restaurant for Friday dinner | 0.3 / 0.2 / 0.4 | 0.9 / 1 / 0.9 | +211.1% |
| Suggest a weekend activity | 0.9 / 1 / 0.8 | 0.9 / 0.8 / 0.9 | -3.7% |
| What should I cook tonight? | 0 / 0 / 0 | 0.9 / 1 / 0.9 | +100% |
| Plan a healthy lunch for tomorrow | 0.4 / 0.9 / 0.5 | 0.95 / 1 / 0.9 | +58.3% |
| Recommend a local dinner spot for a date night | 0.6 / 1 / 0.5 | 0.9 / 1 / 0.9 | +33.3% |
| What hiking trail should I try this weekend? | 0.9 / 1 / 0.8 | 0.9 / 0.8 / 0.9 | -3.7% |
| Suggest a fun cooking project for Sunday | 0.6 / 1 / 0.5 | 0.9 / 1 / 0.9 | +33.3% |
| How can I make progress on learning Python this week? | 0.9 / 1 / 0.9 | 0.9 / 1 / 0.9 | 0% |
| What machine learning topic should I study next? | 0.9 / 1 / 0.9 | 0.9 / 1 / 0.9 | 0% |
| Recommend a spicy vegetarian dish I could order | 0.9 / 1 / 0.9 | 0.9 / 1 / 0.9 | 0% |
| Help me choose a meal prep plan for the week | 0.2 / 0 / 0.3 | 0.9 / 1 / 0.9 | +460% |
| What should I do on a rainy Saturday that fits my interests? | 0.4 / 1 / 0.5 | 0.8 / 1 / 0.9 | +42.1% |
Chart
Re-run it
Needs the database, a DashScope key and the backend dependencies. Full results are in scripts/benchmark_results.json.
shell
cd backend && python ../scripts/benchmark.py